If you run a business in Allen, Texas, you already know the drill. Your customers are on their phones before they're even out of bed, checking notifications, booking appointments, ordering..
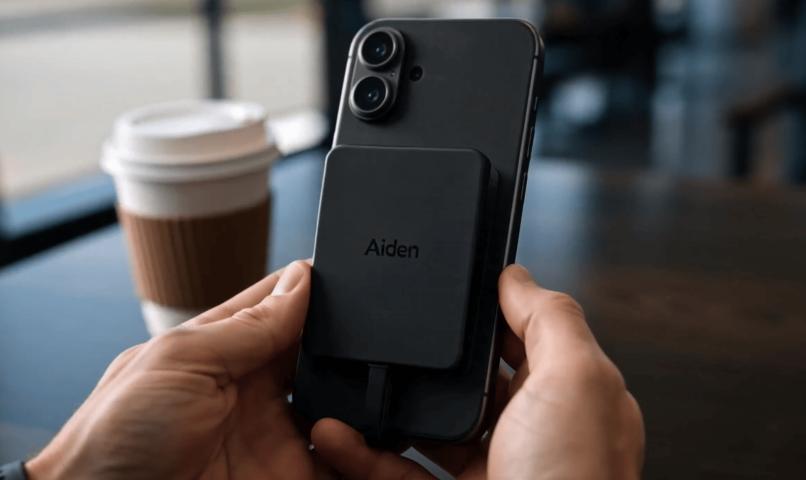
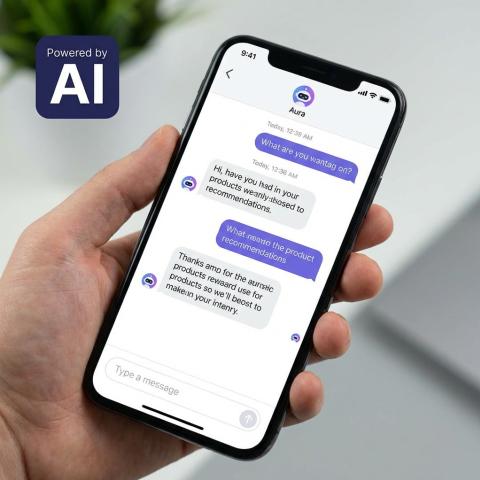
A mobile AI agent is software — or a small device — that can actually operate your phone for you: opening apps, tapping, typing, and completing tasks end to end,..
Mobile apps are no longer optional digital assets for growth-focused companies. They have become core business tools that support customer engagement, operational efficiency, data collection, and long-term brand loyalty. For..
In today’s hyper-connected digital economy, mobile applications are no longer optional—they are foundational to how businesses engage customers, streamline operations, and drive growth. From startups to global enterprises, organizations are..
In 2026, the question is no longer whether mobile matters. It’s whether your business is ready for what mobile has become.Smartphones are now the first screen people check in the..
Mobile app development is evolving at an unprecedented pace. As technology
advances, user expectations grow, and businesses compete to deliver seamless
digital experiences, staying updated with the latest trends has..
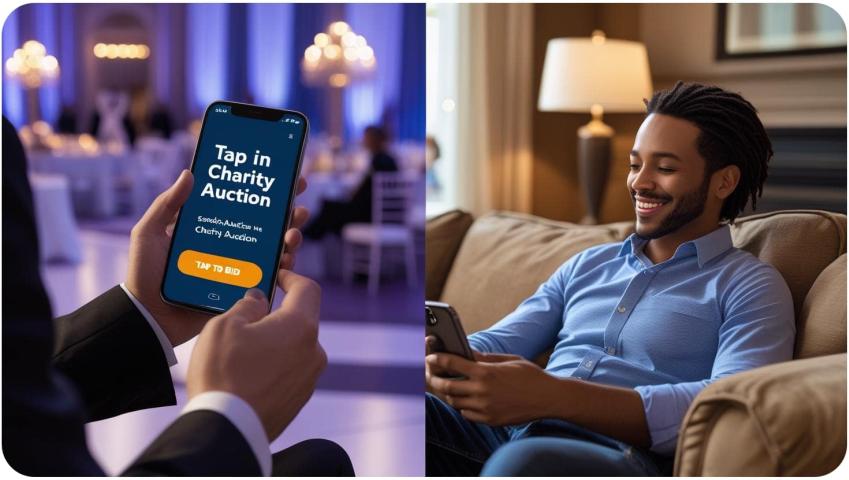
If you’re still running your charity gala with clipboards and golf pencils, you are essentially asking your donors to do manual labor to give you money. I’ve been on both..
In today’s digital-first economy, mobile applications have evolved far beyond simple tools for communication or entertainment. They are now powerful revenue engines capable of generating consistent, scalable income. While headlines..
App development looks exciting from the outside — millions of downloads, viral growth, and financial freedom. But behind every successful app is a story of sleepless nights, unexpected challenges, and..
The mobile game market has developed into a multi-billion-dollar ecosystem that is changing how we are all engaging with games every day. Hyper casual puzzle games, multiplayer battle arenas, narrative-led..
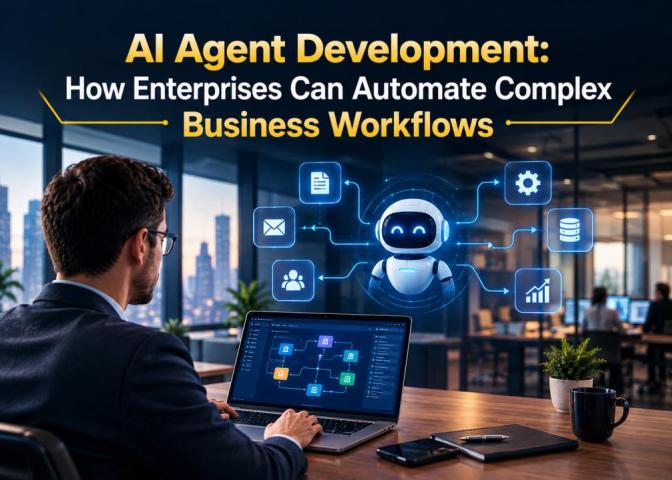
Enterprise automation is moving beyond fixed rules and repetitive task execution.AI agents introduce a different approach to automation. Instead of executing only predefined instructions, an AI agent can interpret an..
Enterprise automation is moving beyond fixed rules and repetitive task execution. Traditional workflow systems are effective when processes follow predictable paths, but modern business operations rarely remain that simple. Customer..
Marketing is now more data-driven, competitive, and demanding than ever. Most businesses need to really understand how customers behave, build personalized journeys, juggle several channels, and keep tweaking campaigns nonstop...
A mobile AI agent is software — or a small device — that can actually operate your phone for you: opening apps, tapping, typing, and completing tasks end to end,..
Quick OverviewAI-powered customer support agents use large language models and natural language processing to respond to customer inquiries automatically, twenty-four hours a day. They integrate with CRM platforms, ticketing systems,..
IntroductionFor decades, businesses have invested in automation technologies to improve efficiency and reduce operational costs. From macros and workflow engines to robotic process automation (RPA), organizations have continuously searched for..
Businesses are changing the way they work. One major reason is the rise of AI agents. These are smart systems that can perform tasks, make decisions, and learn from data...
The rise of AI agents—autonomous systems capable of reasoning, decision-making, and executing tasks—has transformed how businesses operate. From customer support automation to enterprise workflow orchestration, AI agents are now at..