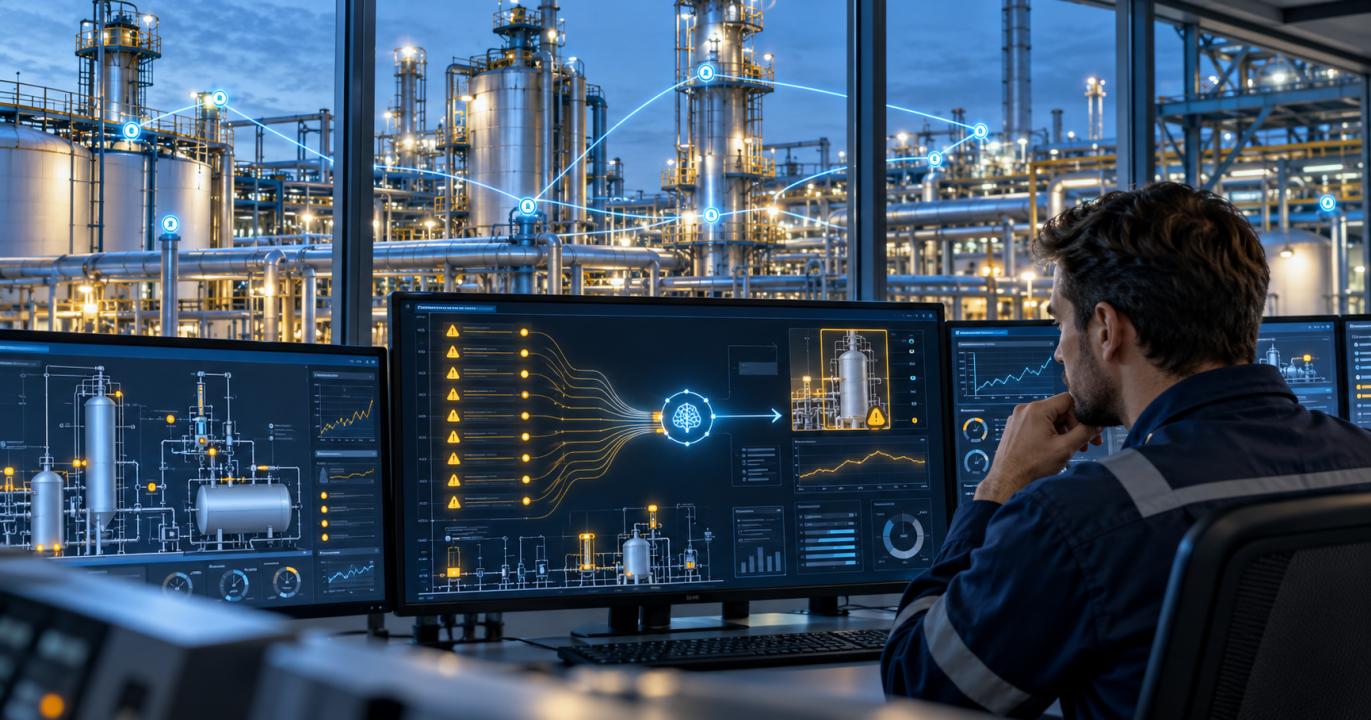
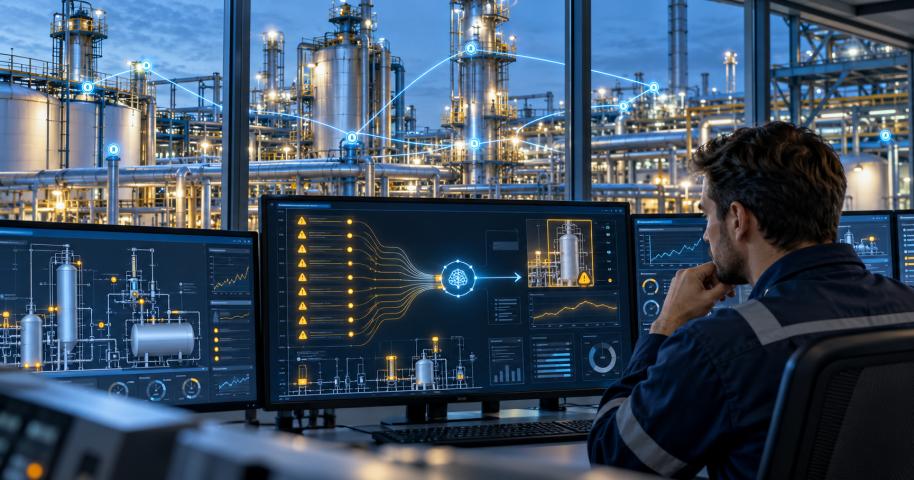
Chemical facilities depend on alarms to warn operators when process conditions move outside safe or expected limits. The challenge is that a single abnormal condition can trigger dozens of related alarms within minutes. When operators face a fast-growing alarm load, the most important signal may be buried beneath secondary alerts, repeated notifications, and disconnected data.
Autonomous AI agents can help by detecting weak signals earlier, correlating related events, identifying the likely initiating condition, and coordinating a response before the situation develops into an alarm flood. Their safest role is not to replace the distributed control system, safety instrumented system, or control-room operator. It is to provide a bounded intelligence layer that helps qualified personnel understand what is changing and act sooner.
Quick Answer
Autonomous agents can proactively reduce alarm escalation by continuously monitoring process and equipment data, recognizing abnormal combinations of signals, grouping alarms that share a probable cause, and recommending approved response steps. They can also retrieve procedures, notify the correct personnel, create maintenance actions, and verify whether assigned tasks were completed.
However, an AI agent should not independently suppress critical alarms, change trip limits, modify safety logic, or take unrestricted control of hazardous processes. In a chemical facility, safety-critical decisions must remain governed by established alarm-management practices, process safety controls, management of change, cybersecurity requirements, and human accountability.
What Does Alarm Escalation Mean in a Chemical Plant?
Alarm escalation occurs when an abnormal operating condition generates an increasing number of alarms, demands progressively more urgent intervention, or develops into a more serious process safety event.
For example, declining cooling-water flow may initially appear as a small flow deviation. If it is not recognized, reactor temperature may rise, pressure may increase, product quality may deteriorate, and several downstream alarms may activate. Each alarm is technically valid, but many are consequences of the same initiating problem.
Alarm escalation becomes especially difficult when:
- Multiple assets are interacting.
- Alarms arrive faster than operators can assess them.
- The initiating event occurs well before a high-priority alarm.
- Data is divided among the DCS, historian, condition-monitoring system, maintenance platform, and laboratory system.
- Nuisance or standing alarms have reduced operator trust.
- The facility is starting up, shutting down, changing grades, or operating under an unusual constraint.
- Procedures and equipment histories are difficult to retrieve during an abnormal situation.
Conventional alarm systems identify predefined threshold violations. They do not always explain why several alarms appeared together, what is likely to happen next, or which response should receive attention first. This is the gap a carefully governed AI operations agent can help close.
How Autonomous Agents Can Prevent Alarm Escalation
1. Detect weak signals before a threshold alarm activates
Many failures develop gradually. A pump may show rising vibration, lower discharge pressure, and a small increase in motor current before any individual measurement crosses its alarm limit. An AI agent can evaluate the combined pattern and flag the change as an emerging abnormal condition.
This early-warning capability gives the operations team more time to inspect the asset, shift load, prepare a standby unit, or schedule controlled maintenance. The agent does not need to predict the exact time of failure to be useful. It needs to identify that current behavior is becoming materially different from the validated normal range.
2. Correlate related alarms and identify a probable initiating event
An alarm flood often contains a mixture of root-cause alarms and consequential alarms. An agent can use asset relationships, event sequences, process topology, and historical incidents to group alarms that may share a cause.
Instead of presenting 25 disconnected notifications, the agent might summarize:
Cooling-water header pressure declined before the reactor temperature and pressure alarms. Three affected units share the same header. Check the cooling-water supply and pump status first.
This type of summary reduces search time. It must also show the source signals, timestamps, confidence level, and alternative explanations so the operator can verify the reasoning.
3. Prioritize alarms according to operating context
A fixed priority does not always represent the immediate operational risk. The significance of an alarm may change during startup, shutdown, maintenance, batch transition, or equipment bypass.
An agent can add context by considering:
- Current operating mode
- Active work permits and maintenance activities
- Equipment availability and redundancy
- Material being processed
- Recent laboratory results
- Weather or utility constraints
- Other active alarms and interlocks
- Approved operating limits and procedures
The agent can then recommend which condition should be assessed first. Any dynamic prioritization, suppression, shelving, or state-based alarming must follow the site's approved alarm philosophy and engineering controls. AI should not silently hide safety-relevant information.
4. Retrieve the correct procedure at the point of need
During an abnormal situation, operators may need to consult operating procedures, alarm-response instructions, equipment manuals, safety data, or previous shift notes. Searching several systems consumes time and creates the risk of using an outdated document.
A knowledge-enabled agent can retrieve the approved procedure associated with the affected tag, asset, material, and operating mode. It can present the relevant steps, revision number, source link, and required approvals without improvising instructions.
The distinction matters: the agent should retrieve and explain approved guidance, not invent a new emergency procedure.
5. Coordinate action across operations, maintenance, and safety teams
Alarm escalation is often an organizational problem as well as a technical one. The right response may require an operator to stabilize the process, maintenance to inspect an asset, the laboratory to prioritize a sample, and a supervisor to approve a production change.
Within defined permissions, an agent can:
- Notify the appropriate on-duty role.
- Open a maintenance request with relevant tags and evidence.
- Attach trend data and recent work history.
- Request confirmation that an inspection was performed.
- Escalate an overdue action to an authorized supervisor.
- Record who acknowledged each recommendation.
- Maintain a time-stamped incident timeline.
This coordination reduces handoff delays while preserving clear ownership for every decision.
6. Monitor whether the response is working
Issuing a recommendation is not enough. The agent can track the affected variables after the operator takes action and report whether the process is stabilizing.
For example, after a change to cooling flow, the agent might state that reactor temperature is returning toward its normal range but jacket differential pressure remains abnormal. If the condition continues to deteriorate, the agent can re-alert the operator and suggest the next approved escalation path.
7. Identify recurring nuisance and standing alarms
Repeated alarms can normalize abnormal conditions and consume operator attention. An agent can analyze alarm history to identify chattering alarms, frequent short-duration alarms, stale alarms, repeated shelving, and alarm combinations associated with no operational response.
These findings should feed the formal alarm-management lifecycle. Engineers can then rationalize alarms, correct instrumentation problems, revise logic, or improve procedures through established review and management-of-change processes. The agent can support the analysis, but it should not autonomously remove alarms from service.
8. Learn from incidents and near misses under human review
Near misses contain valuable information about failure sequences, communication gaps, and inadequate safeguards. An AI agent can compare a live condition with reviewed event patterns and warn that the facility is approaching a previously observed scenario.
The underlying incident data must be accurate, appropriately classified, and approved for use. Lessons learned should be validated by process safety and operations specialists before becoming part of the agent's decision logic.
Example: Preventing a Reactor Alarm Flood
Consider a reactor whose temperature is controlled by a cooling-water loop.
- The agent detects a gradual reduction in cooling-water flow, a small rise in pump vibration, and increasing control-valve demand.
- No high-temperature alarm has activated, but the combined pattern differs from validated normal operation.
- The agent checks the asset hierarchy and finds that the pump supplies two reactor trains.
- It reviews current operating mode, maintenance status, recent work orders, and the approved alarm-response procedure.
- The agent notifies the console operator that cooling capacity may be degrading and presents the supporting trends.
- It recommends verification of the pump and standby availability according to the approved procedure.
- With operator approval, it creates a priority inspection request and alerts the shift supervisor.
- The agent monitors the process response and confirms whether cooling flow recovers or the risk continues to increase.
This workflow may prevent the initial deviation from becoming a chain of temperature, pressure, utility, and downstream alarms. The operator remains in control, while the agent shortens the time required to connect the evidence and coordinate action.
Reference Architecture for a Chemical-Facility Operations Agent
An effective architecture separates decision support from safety-critical protection.
Data and source layer
The agent may receive approved, preferably read-only data from:
- Process historian and DCS interfaces
- Condition-monitoring and vibration systems
- Fire and gas monitoring interfaces
- MES and batch systems
- LIMS and quality systems
- CMMS or EAM platforms
- Shift logs, procedures, manuals, and alarm-response documents
- Work permits and maintenance schedules
Direct connectivity to operational technology should be tightly controlled. Where possible, data should pass through segmented, monitored interfaces rather than giving the model unrestricted access to the control network.
Context and knowledge layer
Raw tags are not enough. The agent needs governed context such as asset hierarchies, process relationships, alarm priorities, safe operating limits, operating modes, approved procedures, document versions, and ownership roles.
Analytics and agent layer
Different components may perform anomaly detection, event correlation, forecasting, document retrieval, workflow orchestration, and natural-language explanation. Deterministic rules should enforce hard boundaries where a probabilistic model is inappropriate.
Governance and policy layer
The system should enforce role-based access, approved tools, escalation policies, confidence thresholds, data restrictions, human approval points, and prohibited actions. Every recommendation, data source, user response, and downstream action should be logged.
Operator experience layer
Operators need concise, evidence-based information rather than another stream of alerts. The interface should show what changed, why the agent considers it significant, what evidence supports the conclusion, the approved response source, and what action requires human approval.
Monitoring and assurance layer
The agent itself requires continuous evaluation. Teams should monitor false alerts, missed conditions, latency, model drift, unavailable sources, retrieval quality, cybersecurity events, and user overrides. Changes to models, prompts, tools, and integrations should be versioned and tested.
The Right Level of Autonomy
The word autonomous can be misleading in a high-hazard environment. A safer deployment model increases permissions gradually.
Level 1: Offline analysis
The system analyzes historical alarms and incidents without influencing live operations. This validates data quality, event sequences, and potential use cases.
Level 2: Read-only shadow monitoring
The agent evaluates live data and records what it would have recommended, but operators do not depend on its output. Teams compare its findings with actual events and operator decisions.
Level 3: Advisory assistance
The agent presents early warnings, explanations, and approved procedural guidance. Operators decide what action to take.
Level 4: Approved workflow execution
With human approval, the agent can perform low-risk digital actions such as creating work orders, sending notifications, assembling reports, or requesting inspections.
Level 5: Bounded operational action
Any direct process action requires a much higher standard of engineering review, hazard analysis, cybersecurity, validation, testing, management of change, and regulatory assessment. An AI agent should not be treated as an independent protection layer or allowed to bypass the DCS, SIS, emergency shutdown system, interlocks, or qualified operators.
For most facilities, the strongest near-term value lies in Levels 2 through 4.
Implementation Roadmap
1. Fix the alarm-management foundation
Review the alarm philosophy, priority rules, rationalization records, standing alarms, nuisance alarms, shelving practices, and operator workload. AI cannot compensate for fundamentally poor alarm design.
2. Choose one bounded use case
Begin with an observable problem such as recurring compressor trips, cooling-system degradation, distillation instability, or utility interruptions. Define the assets, data, users, decisions, and prohibited actions.
3. Establish a safety and governance boundary
Document what the agent may read, recommend, create, or execute. Define mandatory human approvals, fallback behavior, access control, incident response, and audit requirements.
4. Prepare and synchronize the data
Validate tag names, units, timestamps, sampling rates, asset relationships, maintenance history, alarm records, and document versions. Poor time alignment can create convincing but incorrect causal relationships.
5. Build and test in shadow mode
Run the agent against historical events and then live data without operational authority. Include normal operation, startup, shutdown, maintenance, sensor failure, unusual production modes, and previously unseen conditions.
6. Evaluate with operators and engineers
Console operators, control engineers, maintenance teams, process engineers, safety specialists, and cybersecurity personnel should review the outputs. A technically accurate warning is not useful if it arrives too late, lacks evidence, or adds cognitive load.
7. Integrate low-risk workflows first
Begin with retrieval, summarization, notification, work-order drafting, and evidence collection. Add permissions only after performance and controls are demonstrated.
8. Operate under continuous assurance
Monitor performance, investigate errors, test changes, retrain or recalibrate models when necessary, and maintain rollback procedures. Significant changes should pass the facility's formal review and management-of-change process.
Metrics That Show Whether the Agent Is Helping
Success should be measured by operational outcomes, not the number of AI alerts generated. Useful measures include:
- Time from emerging deviation to operator awareness
- Time required to identify the likely initiating condition
- Peak alarm rate during abnormal situations
- Number and duration of alarm floods
- Standing and chattering alarm counts
- Repeated nuisance-alarm frequency
- Percentage of agent warnings judged actionable
- False-positive and missed-event rates
- Time from recommendation to acknowledged action
- Percentage of recommendations with traceable evidence
- Operator workload and trust feedback
- Recurrence of similar incidents or near misses
Metrics should be reviewed by operating mode and asset class. An overall average can hide poor performance during the exact scenarios where support is most important.
Key Risks and Controls
False confidence
An agent can produce a plausible explanation that is wrong. Require source evidence, confidence indicators, alternative hypotheses, and human verification.
Automation bias
Operators may accept a recommendation because it comes from an AI system. Training should reinforce that the agent is decision support and that approved procedures and professional judgment take precedence.
Data failure
Missing tags, faulty sensors, inconsistent timestamps, or delayed historian feeds can distort conclusions. The agent should detect degraded inputs and clearly state when it cannot make a reliable assessment.
Model drift
Process conditions change after equipment modifications, feedstock changes, control tuning, or production transitions. Performance must be monitored and models revalidated when the operating envelope changes.
Cybersecurity exposure
Connecting an agent to OT and enterprise systems expands the attack surface. Network segmentation, least-privilege access, secure model endpoints, identity controls, allowlisted tools, audit logging, and tested incident response are essential.
Uncontrolled actions
The system must prevent the agent from changing setpoints, trip limits, alarm priorities, interlocks, or safety logic outside an approved engineering workflow. Tool permissions should enforce this restriction technically, not merely state it in a prompt.
How Intellectyx Can Support This Use Case
Intellectyx can help chemical manufacturers design and deploy a bounded AI operations assistant that connects approved plant data, enterprise systems, and governed knowledge sources. The work can begin with a read-only pilot focused on one alarm-escalation scenario, followed by shadow-mode evaluation, operator validation, controlled workflow integration, and ongoing AI monitoring.
Related resources include Intellectyx's guide to an AI operations assistant for chemical manufacturing plants, its overview of AI solutions for manufacturing safety, and its approach to agentic AI for manufacturing.
Mini CTA
Concerned that weak process signals are turning into alarm floods? Start with one high-value unit, connect read-only operational data, and evaluate an AI agent in shadow mode before expanding its role.